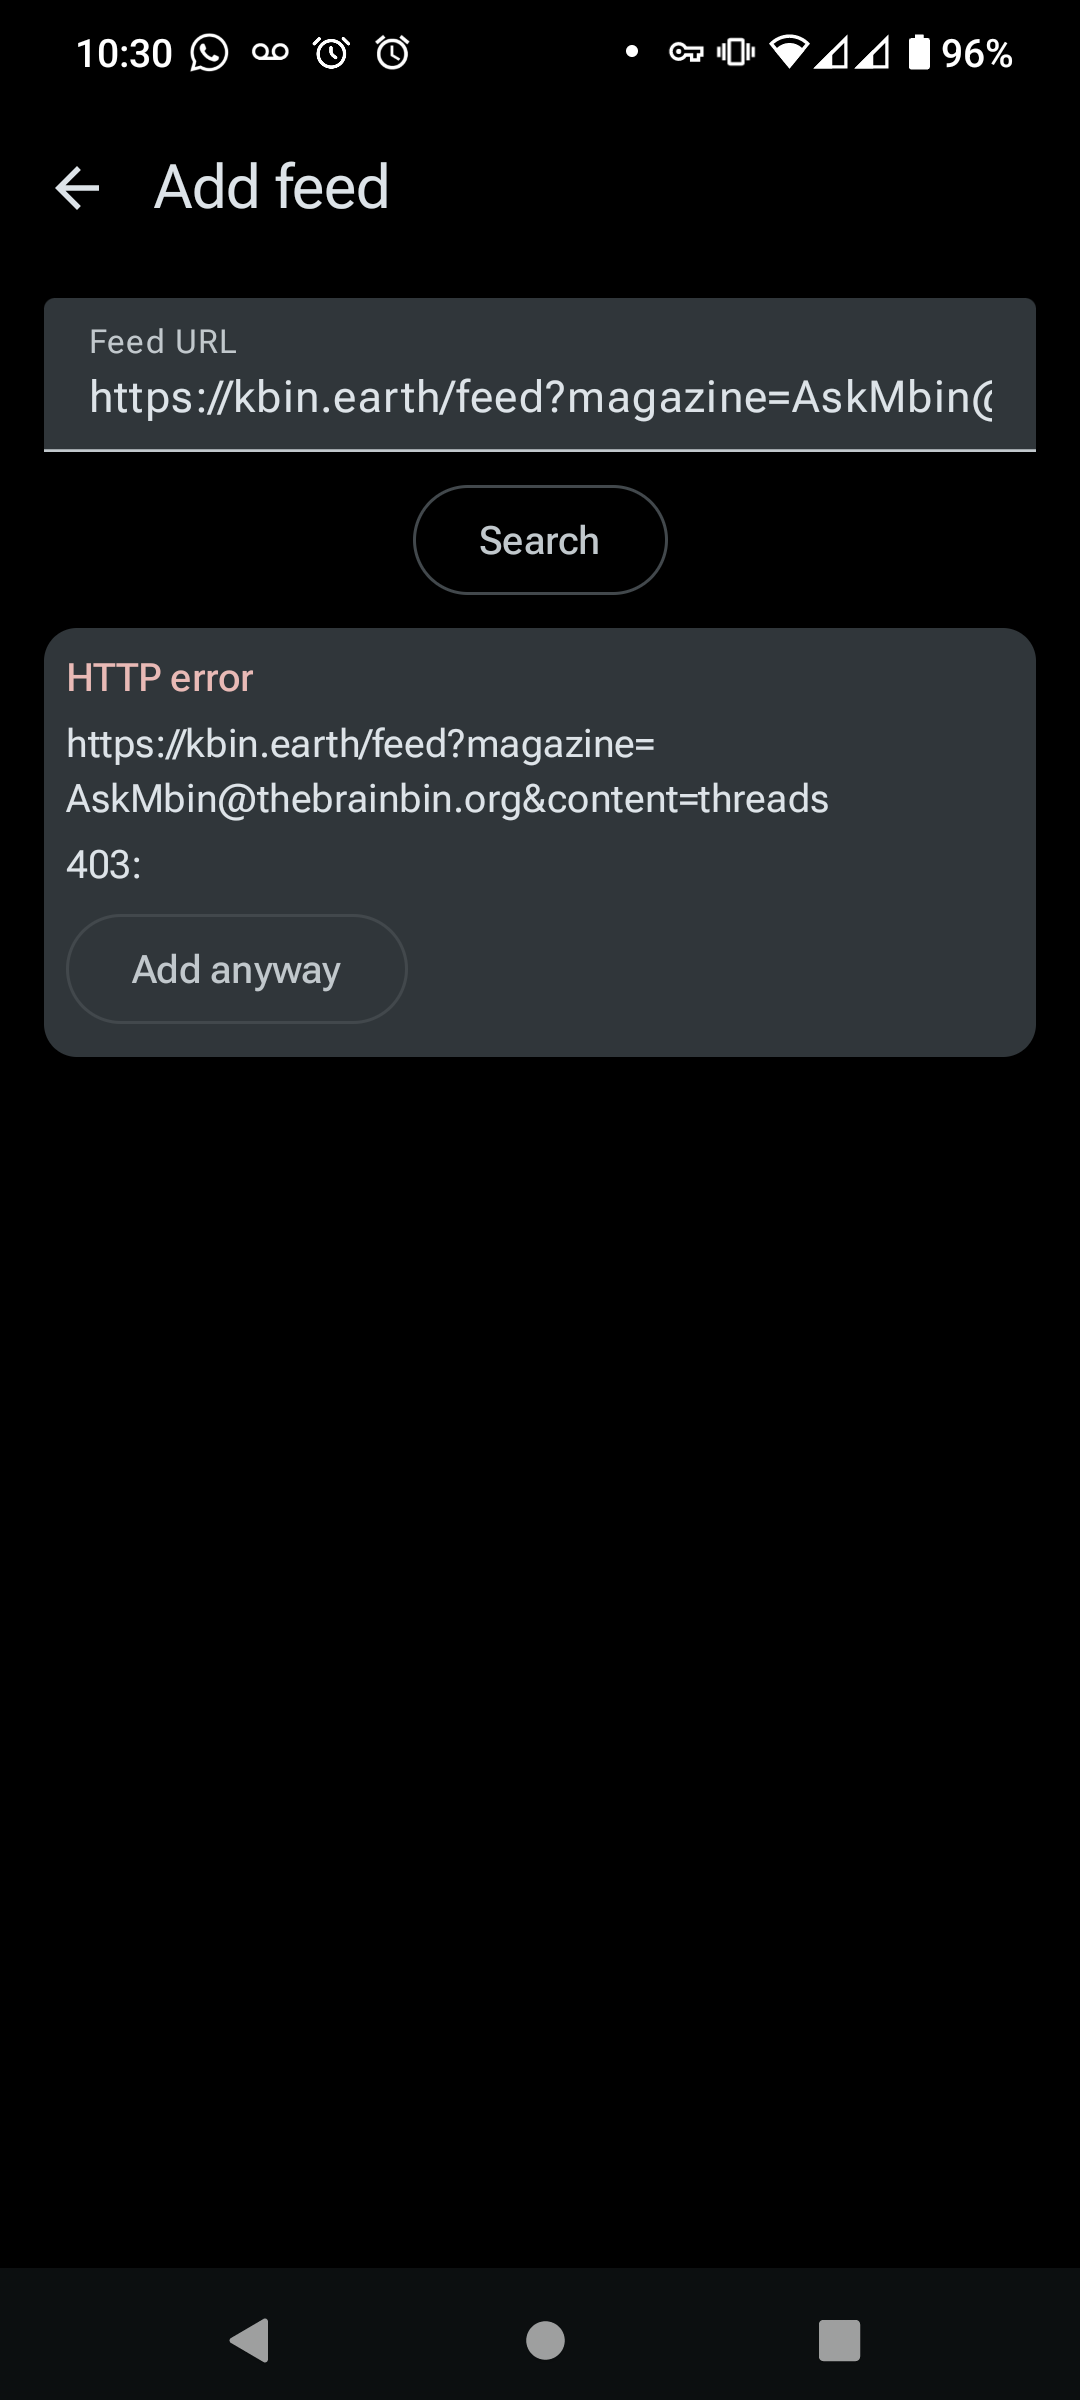
(3/4) (Just remembered I could send albums through my alt)
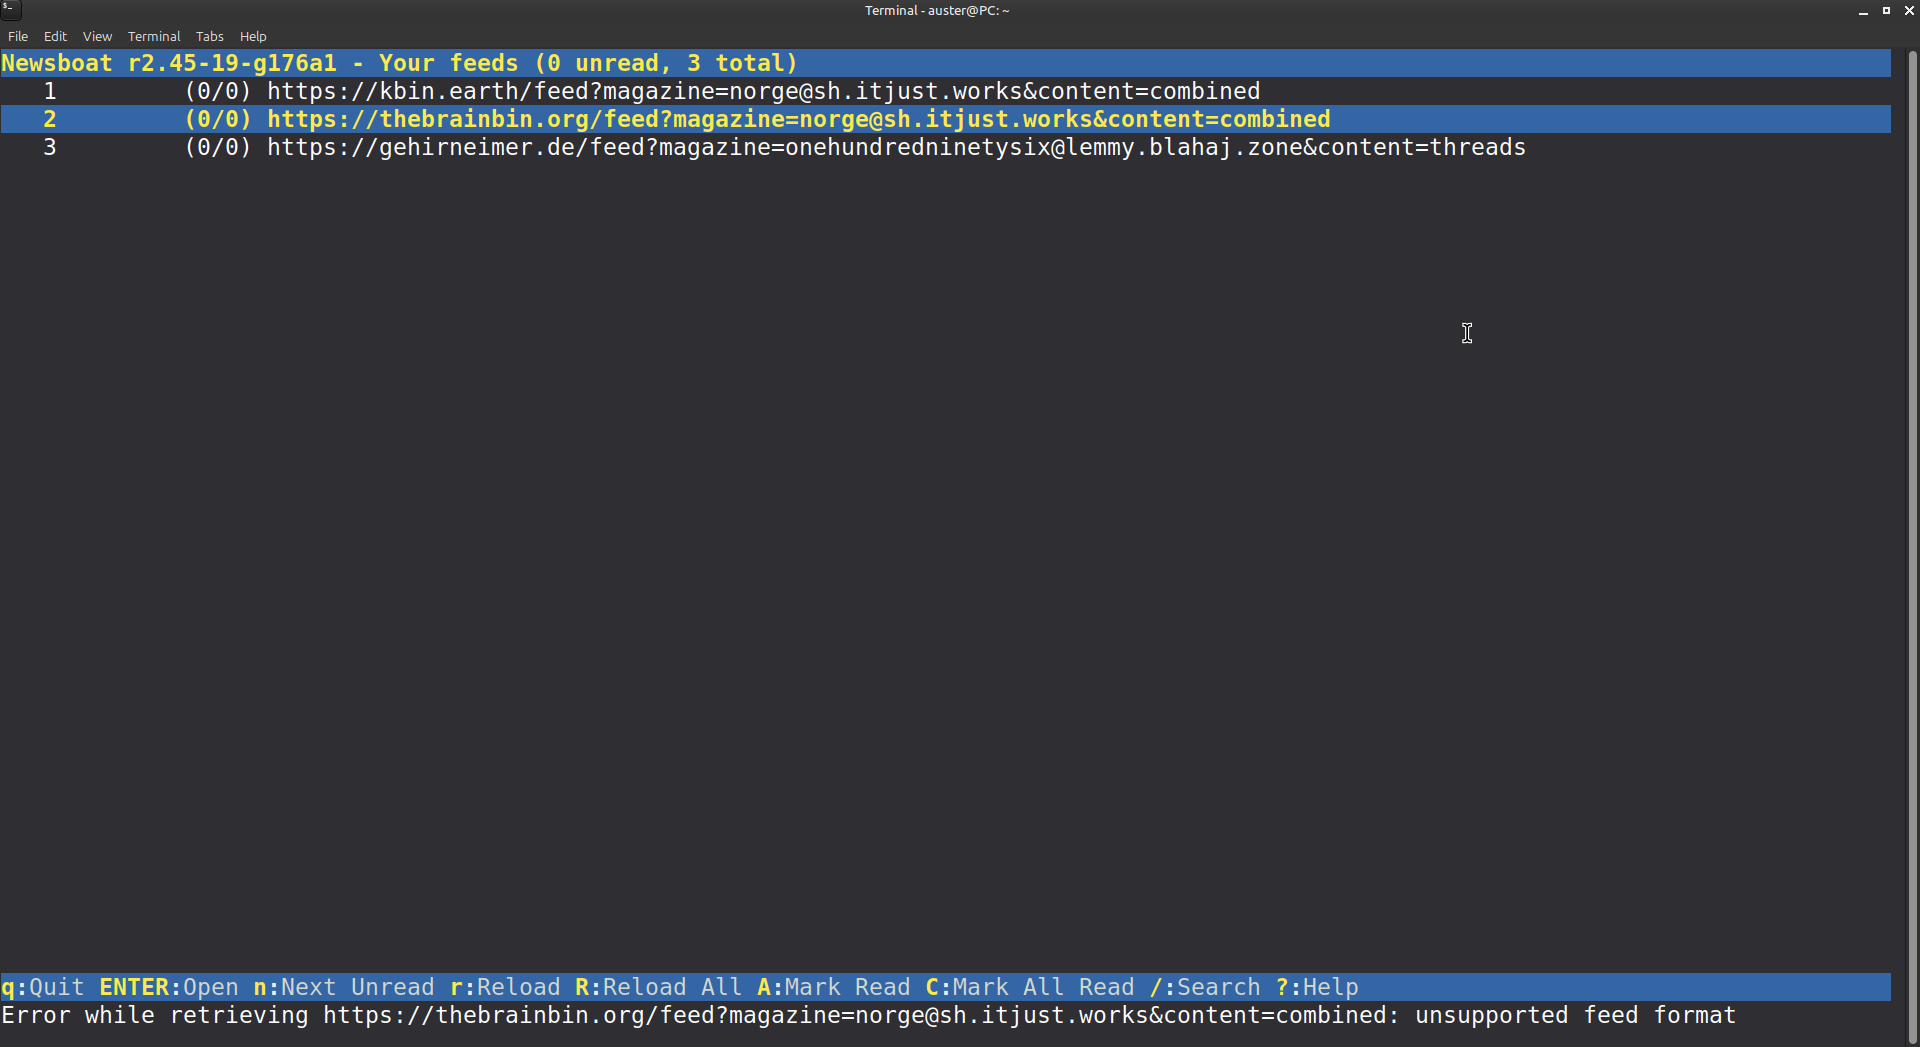
TBB & https://kbin.earth errors on Newsboat when trying to reload feeds during my tests at the time of writing the post:
Attachment: files.mastodon.social ↗
Comment on Are the new RSS feeds misbehaving?
 auster@thebrainbin.org@thebrainbin.org 3 weeks ago
(2/4) Kbin.Earth's error on Feeder:
 Auster1@mastodon.social 3 weeks ago
(3/4) (Just remembered I could send albums through my alt)
TBB & https://kbin.earth errors on Newsboat when trying to reload feeds during my tests at the time of writing the post:
 blued_gear@fedia.io 3 weeks ago
You can send albums, but unfortunately Mbin can not read them.
auster@thebrainbin.org@thebrainbin.org 3 weeks ago (4/4) Remembered I could ask some AI to make things easier.
For kbin.earth feed, Grok says it's Cloudflare bot protection, likely because neither Newsboat or Feeder pass a valid browser agent.
For TBB, Grok for some reason had a hiccup, so asked GPT-5.4 on DuckDuckGo's AI bridge, and it said:
The problem is that the URL is not returning a valid RSS/Atom feed. It’s returning an HTML login page instead, so feed readers see a normal webpage with <form>, <input>, etc., not feed XML. That’s why one reader says “no feeds on the page,” another says “unsupported feed format,” and another says “malformed xml string.”
From the pasted page, the site is protected by login and the feed endpoint appears to require authentication or is redirecting to the login page. The presence of a CSRF token and sign-in form confirms the response is HTML, not feed data.
 BentiGorlich@thebrainbin.org 3 weeks ago
oh okay, well yeah I enabled the "force users to login" option, because the scrapers are just causing tremendous load otherwise. On gehirneimer it is currently disabled so maybe that is the sole reason?
blued_gear@fedia.io 3 weeks ago So it is just the login requirement or did I miss something else? Allowing anonymous access to the endpoint would solve it then, but makes it also easy for scrapers to fetch content.
auster@thebrainbin.org@thebrainbin.org 3 weeks ago Seems to be the case? Left an instance of Newsboat running as I went to do my chores, and just checking now, it already fetched a few communities' posts.
Though it seems concerning to me that scrappers are getting past the current protections. (Hopefully I'm not one of them, considering how much I still follow...)
The error with kbin.earth is likely that the
/feedendpoint is not excluded from the Cloudflare protection.cc @jwr1
It should be working right, as long as the RSS client sends an
Acceptheader equal toapplication/rss+xml.I just ran a
curl https://kbin.earth/feed -H 'Accept: application/rss+xml'command, and it did return the expected RSS XML response.